Use case 01
Internal LLM & RAG Platforms
Private assistants and copilots over enterprise documents, tickets and systems of record.
Running these on dedicated infrastructure keeps internal knowledge inside the perimeter while giving teams OpenAI-compatible endpoints.
GPU considerations
- Memory: model size per endpoint
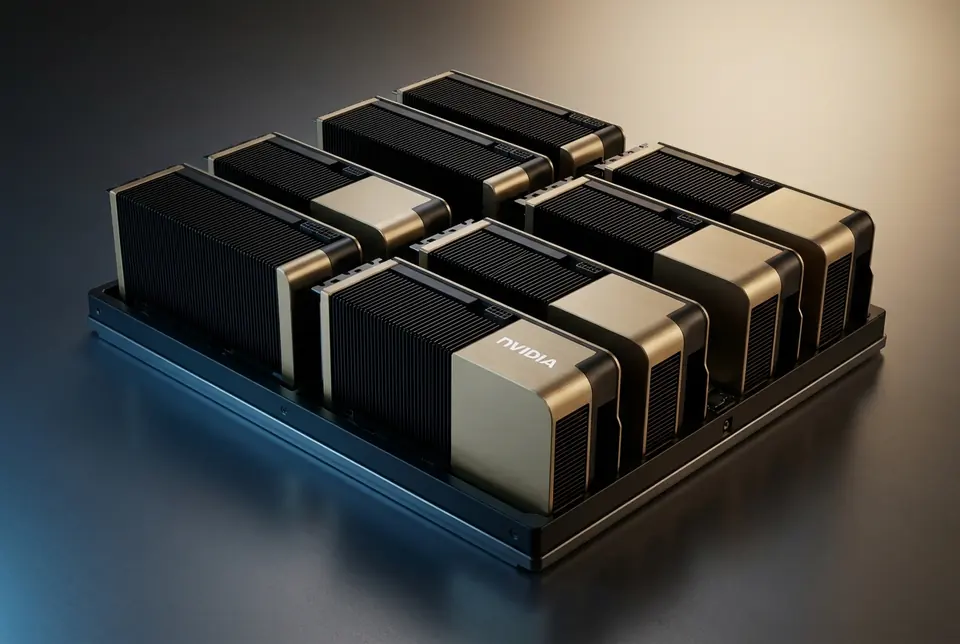
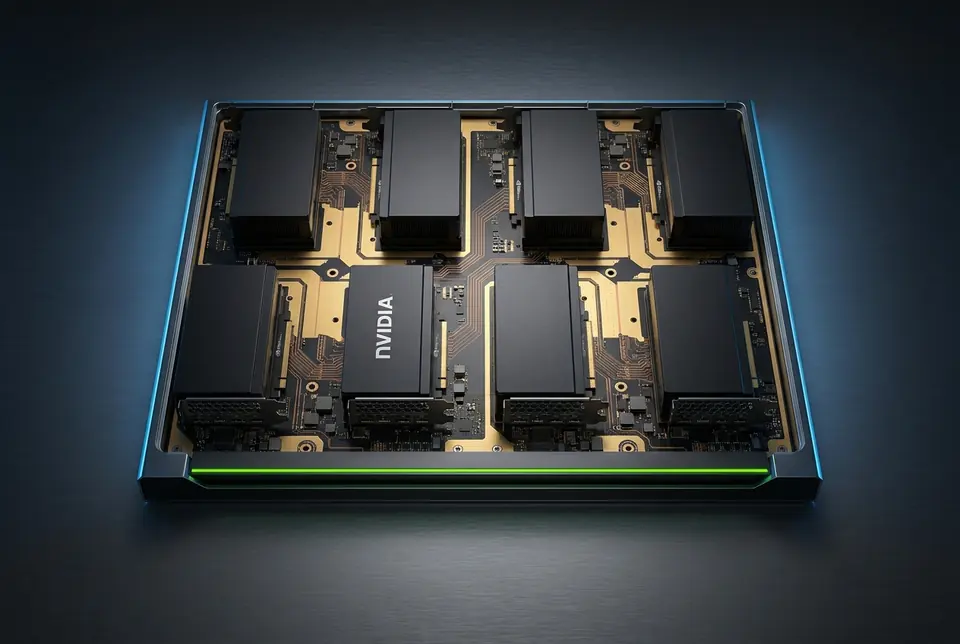
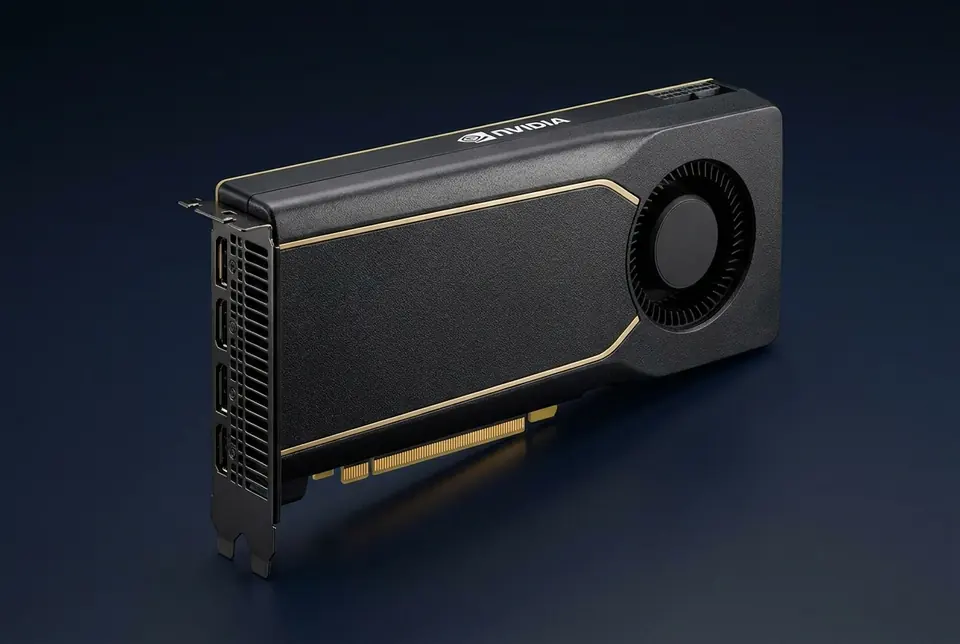
- Interconnect: HGX for large models, PCIe for replicas
- Storage: vector and document stores
- Data residency: enterprise data stays in Australia